Restated Financials, Footnotes, and Data Quality APIs: How to Track Revisions, Validate Fundamentals, and Build Trustworthy Financial Models

Financial statements are routinely treated as fixed, authoritative records by automated ingestion tools. In reality, financial data changes after initial reporting and must be tracked systematically through restatements, amended filings, and expanded disclosures. Any systematic strategy that treats financial data as static operates with a latent structural defect, leading to invalid backtests, audit failures, and severe model drift.
Institutional workflows explicitly track as-reported financials, restated data, and filing-level revision histories to maintain integrity. Retail and mid-tier models typically overwrite historical data with the latest available figures, erasing the context of what the market knew at a specific point in time.
This article explores how to access financial statement footnotes, track restatements, and validate financial data using structured APIs. It focuses exclusively on revisions to reported financial data, including restatements, amended filings, and disclosure changes. It does not cover analyst upgrades or price target changes, which reflect expectations rather than underlying accounting reality.
Financial Statement Revisions vs Analyst Revisions
Financial statement revisions correct previously reported historical data directly at the source. They originate from regulatory filings such as 10-K annual reports, 10-Q quarterly reports, and 8-K amendments. These updates reflect accounting corrections, compliance mandates, or necessary disclosure changes forced by auditors.
Analyst revisions update forward-looking expectations based on external modeling. They originate from equity research analysts on the sell-side and reflect shifts in sentiment rather than material changes to historical facts. Conflating the two introduces severe look-ahead bias into backtesting environments.
Financial statement revisions change what is demonstrably true regarding historical performance. Analyst revisions merely change the consensus of what the market expects moving forward.
Why Restatements, Footnotes, and Filing-Level Data Are Core to Financial Analysis
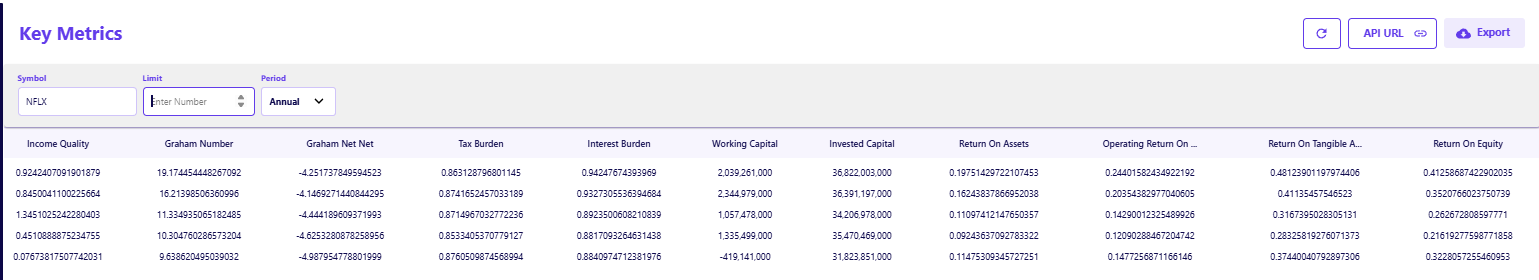
Core financial statements present outcomes at a highly aggregated level that often masks operational friction. Aggregated metrics obscure the underlying accounting assumptions used by management to calculate top-line figures, requiring analysts to pull Key Metrics API before diving into the footnotes. Footnotes and restatements explain exactly how those outcomes were derived and whether prior data series can still be trusted.
Footnotes and restatements explain exactly how those outcomes were derived by executive teams. They clarify what changed after initial reporting and dictate whether prior data series can still be trusted. Without this layer, analysts building a hybrid model risk relying on outdated accounting assumptions.
Reported data is not the same as validated data. Integrating filing-level revision history systematically reduces backtesting error rates because it enforces strict point-in-time accuracy, ensuring models only train on the exact data the market possessed on any given historical date. Real market reactions are based on what was published on the filing date, making point-in-time accuracy a structural requirement.
Where Can I Get Detailed Balance Sheet Footnotes and Restatements?
Detailed balance sheet footnotes and restatements are sourced from primary filings on SEC EDGAR or structured institutional platforms like Audit Analytics, Compustat, and FactSet. Primary sources provide the raw legal text for manual review, while structured sources normalize the disclosures into machine-readable formats for quantitative screening. Analysts use these combined layers to validate baseline metrics against retroactive accounting changes.
The SEC EDGAR database serves as the ground truth for annual and quarterly reports, which contain comprehensive textual footnotes. Standalone filings deliver immediate restatement announcements and non-reliance notices when historical financials can no longer be trusted.
Company investor relations pages also provide supplemental disclosures and earnings materials. Relying on presentation decks introduces risk because management teams often frame non-standard metrics favorably. Regulatory filings strictly enforce standardized disclosure requirements to maintain market integrity.
Which APIs Include Historical Revisions of Financial Statements
Historical financial statement revisions are included in APIs from providers like Financial Modeling Prep, SEC-API.io, Calcbench, and FactSet. These providers offer access to both original as-reported data and fully restated metrics to track how numbers evolve over time. While basic data feeds silently overwrite historical values, specialized filing-level APIs preserve the exact revision timeline for institutional backtesting. Platforms like Financial Modeling Prep act as core infrastructure by explicitly separating as-reported and restated datasets to support strict point-in-time validation workflows.
Programmatic extraction requires an API that preserves point-in-time accuracy without overwriting past numbers. This active preservation prevents look-ahead bias and secures backtest integrity. Pulling original reported financials provides the exact baseline needed to measure subsequent revisions accurately. Establishing this baseline allows models to track revision deltas algorithmically and maintain point-in-time accuracy across multi-year backtests.
A practical workflow implements automated delta tracking by comparing original outputs against restated events continuously through structured APIs. Systems must ingest the original filing data, scan for amended filings, and isolate the exact numerical differences to generate secure audit trails.
Which APIs Provide Quality Checks and Flags for Restated Fundamentals
Quality checks and restatement flags are provided by specialized APIs from Audit Analytics, Financial Modeling Prep, Intrinio, SimFin, and direct SEC feeds. These platforms surface distinct signals, including automated restatement flags and SEC Item 4.02 non-reliance disclosures. Quantitative systems use these exact signals to halt trading algorithms or flag specific equities for manual review when historical data is compromised. Financial Modeling Prep specifically enables integration into automated validation pipelines by surfacing structured restatement signals alongside fundamental data.
Beyond direct regulatory flags, unstructured text serves as a powerful supplementary signal for risk detection. Using this data allows systems to scan executive commentary for early warnings of accounting anomalies long before they hit quantitative screens. You must analyze transcripts to build an early warning system for impending numerical restatements.
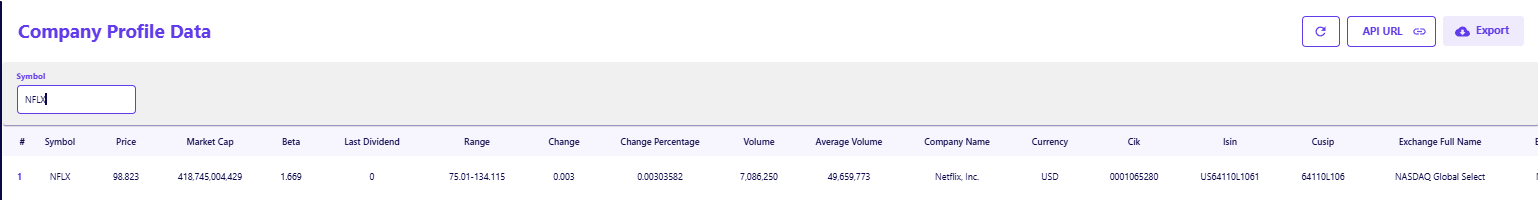
Routing metadata from Company Profile into a broader risk detection pipeline provides an automated signal for governance instability, as sudden auditor changes frequently precede severe data validation failures.
Data quality remains a continuous validation process that requires cross-referencing multiple datasets. Analysts use these APIs to flag non-reliance disclosures automatically and halt algorithms when historical data is compromised. Relying on a single signal often leads to false positives during complex corporate restructurings.
What Differentiates the Best Data Quality and Restatement APIs
The most effective APIs maintain strict separation between as-reported figures and restated financials. Poorly structured data feeds silently overwrite historical data when a company amends an earlier filing. This silent updating creates illusionary arbitrage opportunities in backtests that disappear entirely in live trading environments.
Top-tier providers offer a structured framework for data validation to prevent these systemic failures. As-reported versus restated separation prevents silent historical overwrites that destroy backtest integrity. Revision history tracking maintains a complete timeline of how a specific metric evolved across multiple filings. Timestamp granularity ensures models only ingest data that was publicly available at the exact moment of execution.
The value is not merely accessing financial data, but verifying and validating it systematically. APIs like Financial Modeling Prep specifically enable this structured validation by coupling raw access with comprehensive revision tracking metadata. Systems that cannot prove the origin of a data point hold no utility in a compliance-driven institutional environment.
How Restatement Tracking Fits Into Financial Data Infrastructure
Restatement tracking functions as a translation layer between raw financial data and downstream analytics. It sits directly behind the data ingestion process to enable auditability and immediate risk detection. This positioning explains how professionals evaluate quantitative data feeds based primarily on their revision control mechanisms.
An institutional validation pipeline integrates this by comparing new submissions against previously stored values in real-time. If the system detects a mismatch, it flags the discrepancy and stores the exact numerical deltas for compliance review. Relying on unstructured management commentary acts merely as a supplementary signal for impending restatements before they impact core valuation models.
The structural shift in finance moves away from trusting static financial statements blindly. Infrastructure is now built to validate dynamic, evolving datasets continuously without manual intervention.
Limitations of Restatement and Footnote Data
A primary limitation of footnote data is the severe lack of standardization across corporate filings. Two companies in the exact same sector may classify restructuring costs using entirely different accounting language. This inconsistent taxonomy across providers makes parsing disclosures programmatically difficult and highly prone to false positives.
Parsing errors routinely break automated systems when a table format changes unexpectedly within a regulatory document. Coverage across data providers often remains incomplete for micro-cap equities or international markets, creating massive blind spots for global portfolios. Delays in identifying restatements also pose a significant risk, as non-reliance notices are sometimes buried deep within unrelated filings.
Where Financial Data Validation Breaks Down in Practice
Validation pipelines frequently break down when teams rely solely on the latest reported financials provided by basic data feeds. These tools update historical databases retroactively to reflect current realities, ensuring models trained on this data generate impossible signals. Ignoring a company's restatement history masks deep structural risks and internal control failures within the organization.
Depending on a single data provider introduces a central point of failure into the risk system. If the provider misinterprets a regulatory table, the error propagates through every downstream model unchecked. Redundancy and cross-validation against primary regulatory documents are the only defenses against parser hallucinations.
Building a Financial Data Validation and Audit Pipeline
A resilient validation pipeline follows a strict sequence of ingestion, comparison, validation, flagging, and monitoring. Structured APIs like Financial Modeling Prep enable this architecture by providing the discrete as-reported and revision endpoints necessary to power validation at each distinct pipeline stage. The system must first access raw filings and extract as-reported datasets directly from the source to establish a baseline. It then runs an immediate comparison against previously stored historical versions to cross-validate data points.
Delta computation identifies the exact numerical difference between the original and amended filings. Alerting systems then trigger manual review protocols if the deviation exceeds predefined risk thresholds. The pipeline must ensure consensus through cross-provider validation before executing programmatic trades based on fundamental shifts.
How to Build a Point-in-Time Financial Model Using Restated Data
Building a trustworthy financial model requires enforcing strict point-in-time data integrity across every input. This process ensures that models only use information that was available at the time of prediction, eliminating look-ahead bias and preserving real-world accuracy.
A trustworthy model only uses data that was available at the time of prediction, not restated values introduced later.
For example, if a company reports $1.00 in EPS and later restates it to $1.08, a model trained on the revised figure would incorrectly assume that information was available at the time, introducing look-ahead bias and overstating predictive accuracy.
The process begins by establishing a baseline using as-reported financial data. This dataset reflects the exact figures published at the time of the original filing and serves as the foundation for all subsequent comparisons.
Next, systems track revisions over time by monitoring amended filings, restatements, and updated disclosures. This creates a structured timeline of how each financial metric evolves after initial reporting.
Point-in-time snapshots are then enforced by locking model inputs to the exact data available at each historical timestamp. This prevents models from inadvertently incorporating revised data that was not known to the market at that moment.
Validation layers must then be applied using restatement flags and non-reliance disclosures. These signals identify when previously reported data can no longer be trusted and allow systems to isolate or exclude compromised inputs from the modeling process.
Finally, the validated, point-in-time dataset is fed into the model as a clean and auditable input layer. This ensures that all outputs reflect realistic decision conditions and can be traced back to the exact data available at each step in time.
From Data Access to Data Trust
Financial data is widely commoditized and readily available to any market participant. The competitive advantage belongs to the firm that can prove its data is accurate, point-in-time correct, and fully auditable. Trusted financial data is deliberately constructed through rigorous validation and continuously monitored for retroactive changes. This level of continuous validation is only possible when systems are built on structured, point-in-time APIs that respect historical integrity.
The edge is no longer defined by who has financial data, but by who can detect when that data changes. Firms must validate integrity at the source and build systems that remain accurate in the face of constant revision.
Frequently Asked Questions
What is the difference between as-reported and restated financials?
As-reported financials are the exact, unadjusted numbers a company published on the day of their initial filing. Restated financials are updated figures issued later to correct accounting errors, apply new regulations, or amend previous disclosures.
Why do point-in-time datasets matter for financial modeling?
Point-in-time datasets prevent look-ahead bias by showing a model exactly what information was available on a specific historical date. Overwriting past data with modern restatements causes backtests to rely on information the market did not possess at the time.
How do you find out if a company restated its earnings?
Companies are required to file an 8-K with the SEC under Item 4.02 if their previously issued financial statements can no longer be relied upon. Restatements are also detailed in the footnotes of subsequent 10-K or 10-Q amended filings.
Do standard financial APIs include restatement history?
Many basic feeds overwrite historical data with the latest available figures and destroy revision history. Developer platforms like Financial Modeling Prep preserve both as-reported and restated data to guarantee point-in-time accuracy for rigorous backtesting.
Why are balance sheet footnotes difficult to parse programmatically?
Footnotes consist of dense, unstructured legal and accounting text that varies significantly between companies. Extracting standardized numerical metrics from free-form text requires highly specific parsers and entity extraction models.
What triggers a financial restatement?
Restatements are typically triggered by internal audit findings, SEC comment letters, revenue recognition errors, or the misapplication of accounting principles. They can also result from outright fraud or material misstatements discovered after the fact.

Risk analysis and financial modeling for data-driven market workflows
Parth Sanghvi is a Senior Risk Consultant with experience in financial modeling, valuation, and risk analysis. For FMP, he focuses on translating complex market data and risk models into clear, accessible analysis for developers and investors. His work centers on helping readers understand how institutional-grade financial data applies to real-world workflows and decision-making.
Related




Financial data for every need
Real-time quotes and 30+ years of historical data, including prices, fundamentals, and insider transactions — all accessible via API.
Create Free Account